TERMINAL-BENCH
Benchmark for testing AI agents in real terminal environments
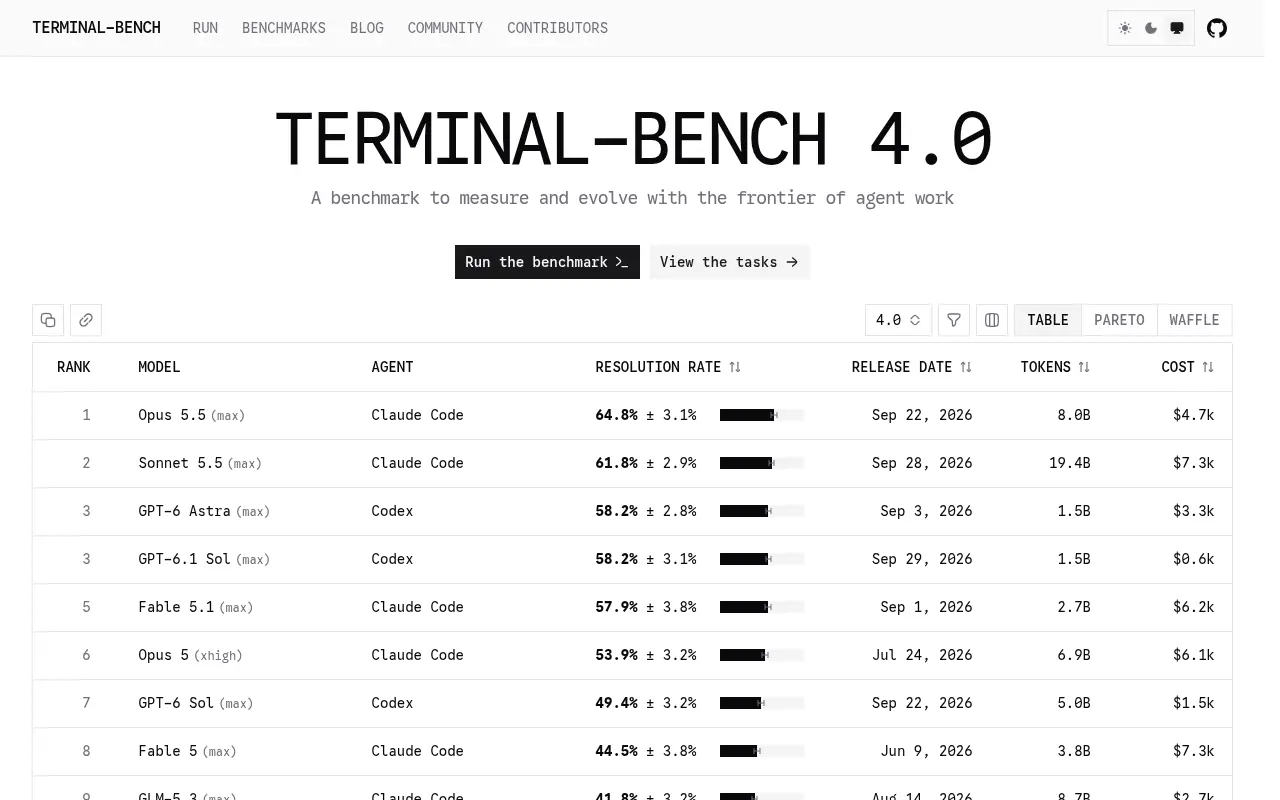 Visit tbench.ai ↗
What is TERMINAL-BENCH?
Terminal-Bench measures how well AI agents perform autonomous, end-to-end tasks in actual terminal settings—from code compilation to model training and server setup. It provides a dataset of ~100 tasks and an execution harness connecting language models to a terminal sandbox. The tool is designed for developers building LLM agents, benchmarking frameworks, or evaluating system-level reasoning. Built with Claude-code and hosted by Stanford, Harbor, and Laude Institute, it tracks model performance with resolution rates and confidence intervals across different agents.
Momentum
Daily activity over the last 30 days: upvotes, unique visits, new GitHub stars and Hacker News points.
How do we know it's vibe coded?
vibetrend discovered TERMINAL-BENCH automatically. Evidence: Trending on gittrend.io: agent files (claude-code) in harbor-framework/terminal-bench-1. View source.
Similar vibe-coded apps
Open-source platform for orchestrating data, AI, and infrastructure workflows
Benchmark suite for code agents controlling robots in physical tasks
Blind-graded benchmark of AI coding models on real planted bugs
Remote MCP server connecting AI agents to data from 91 platforms
Graph database on object storage, built for AI agent memory and context
Benchmark measuring how well AI agents can improve base language models
Evaluation layer for AI analytics with governed ground truth and drift detection