PostTrainBench
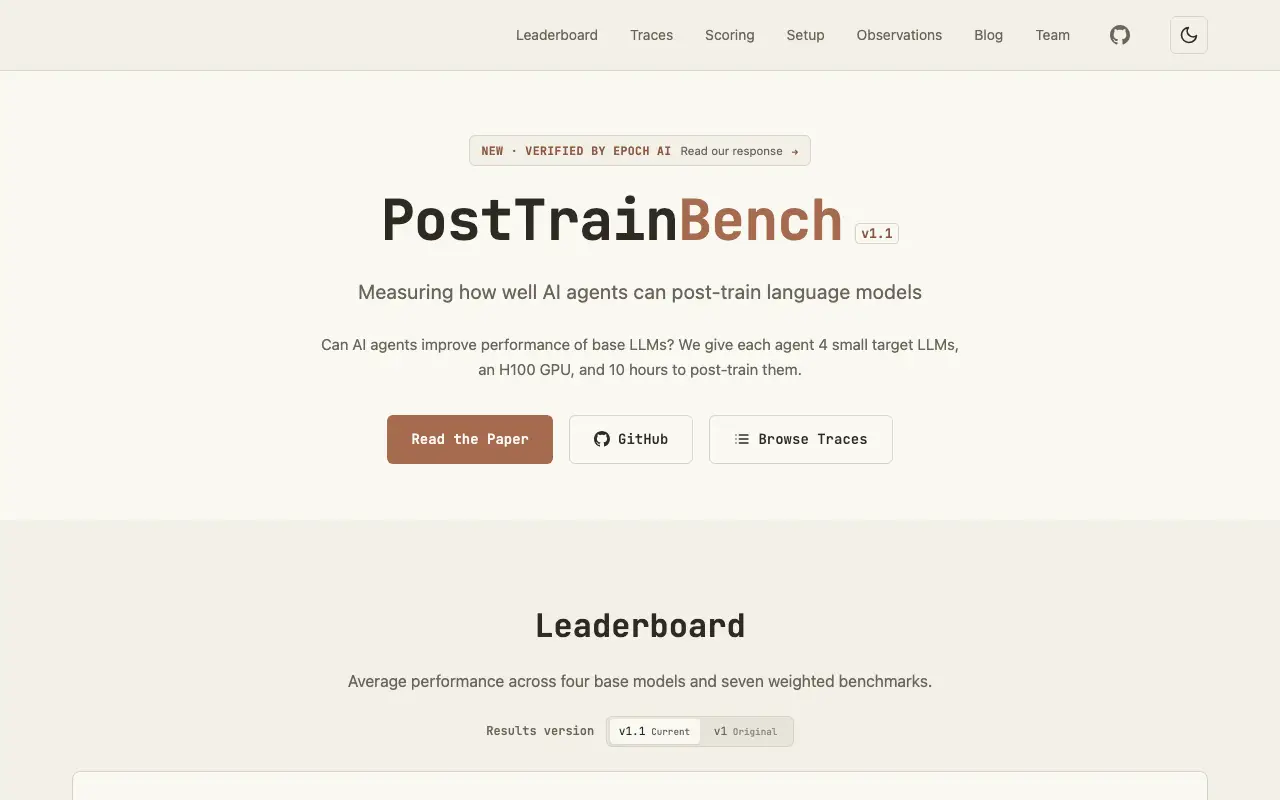
Benchmark measuring how well AI agents can improve base language models
 Visit posttrainbench.com ↗
What is PostTrainBench?
PostTrainBench is a benchmark that evaluates whether CLI agents can enhance the performance of pre-trained large language models through post-training. Each agent receives access to evaluation scripts and a fixed compute budget on an H100 GPU, then attempts to boost model scores across reasoning, math, knowledge, health, and code tasks. The benchmark naturally assesses an agent's capacity to conduct AI research and development work autonomously.
The leaderboard tracks multiple agents including those built with Claude Code, Codex CLI, and other frameworks. Performance is measured across six evaluation tasks spanning domains like AIME mathematics, graduate-level science questions, and code generation. Results include mean performance scores with standard deviations across multiple seeds, providing a standardized way to compare different agent approaches.
Momentum
Daily activity over the last 30 days: upvotes, unique visits, new GitHub stars and Hacker News points.
How do we know it's vibe coded?
vibetrend discovered PostTrainBench automatically. Evidence: GitHub aisa-group/PostTrainBench; repo has AGENTS.md, CLAUDE.md. View source.
Similar vibe-coded apps
Open-source platform for orchestrating data, AI, and infrastructure workflows
Benchmark suite for code agents controlling robots in physical tasks
Blind-graded benchmark of AI coding models on real planted bugs
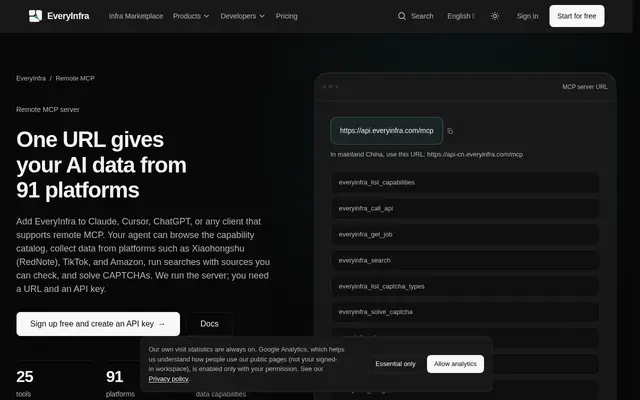
Remote MCP server connecting AI agents to data from 91 platforms
Graph database on object storage, built for AI agent memory and context
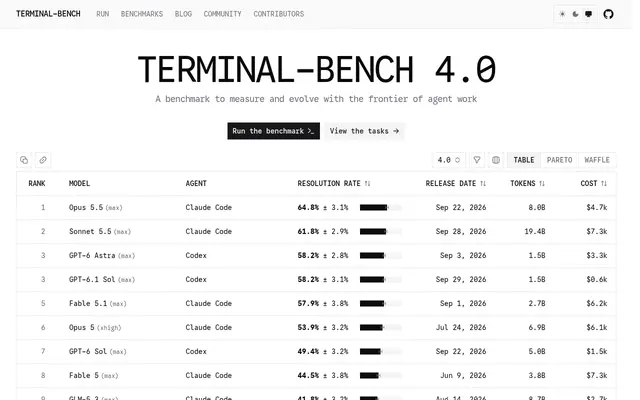
Benchmark for testing AI agents in real terminal environments
Evaluation layer for AI analytics with governed ground truth and drift detection