Bug Hunt Bench
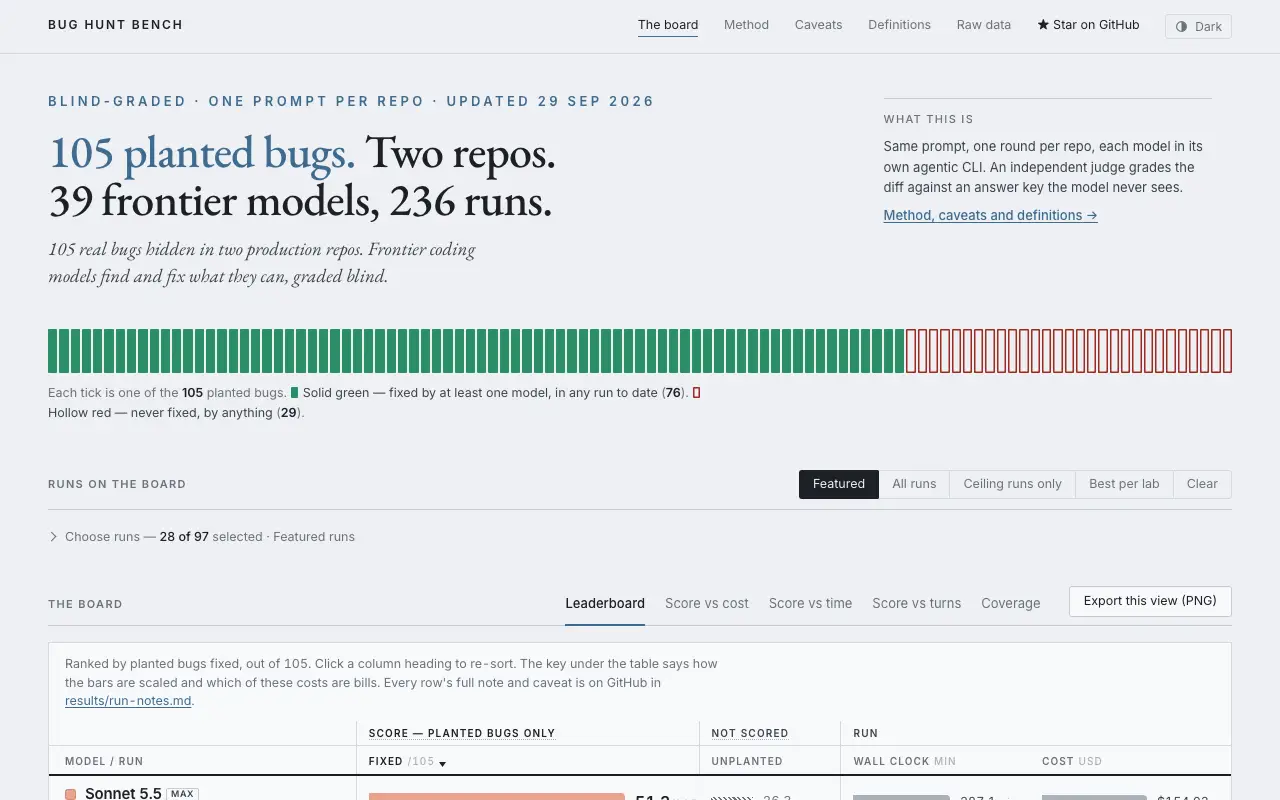
Blind-graded benchmark of AI coding models on real planted bugs
 Visit bughunt.productcompass.pm ↗
What is Bug Hunt Bench?
Bug Hunt Bench is a leaderboard that measures how well frontier coding models find and fix real bugs. The benchmark hides 105 actual bugs across two production codebases, runs each model in its own agentic CLI environment, and grades results blind against a withheld answer key. Only fixed bugs count toward the score; extra fixes are tracked separately.
The site tracks 39 models from labs including Anthropic, OpenAI, Meta, xAI, Google, and others, with 236 runs completed as of September 2026. Each model gets one round per repository. The live leaderboard shows scores, wall-clock time, cost, and coverage, letting developers compare how different AI coding tools perform on real-world bug fixing tasks.
Momentum
Daily activity over the last 30 days: upvotes, unique visits, new GitHub stars and Hacker News points.
How do we know it's vibe coded?
vibetrend discovered Bug Hunt Bench automatically. Evidence: GitHub phuryn/bug-hunt-bench; repo has .claude, CLAUDE.md. View source.
Similar vibe-coded apps
Open-source platform for orchestrating data, AI, and infrastructure workflows
Benchmark suite for code agents controlling robots in physical tasks
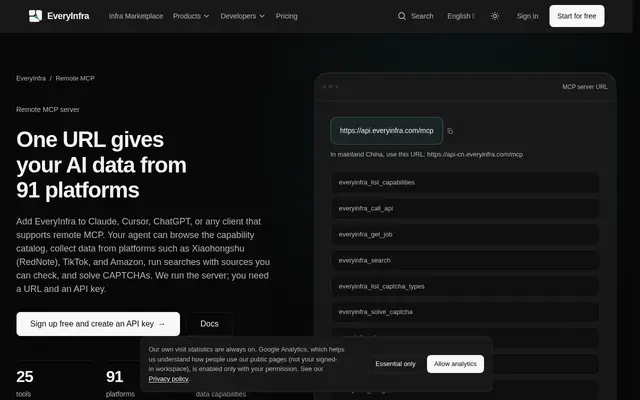
Remote MCP server connecting AI agents to data from 91 platforms
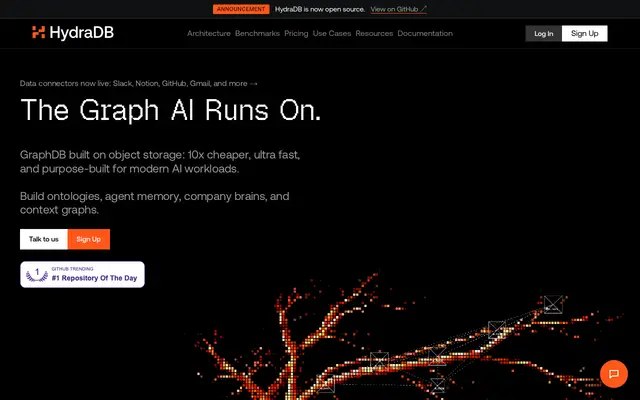
Graph database on object storage, built for AI agent memory and context
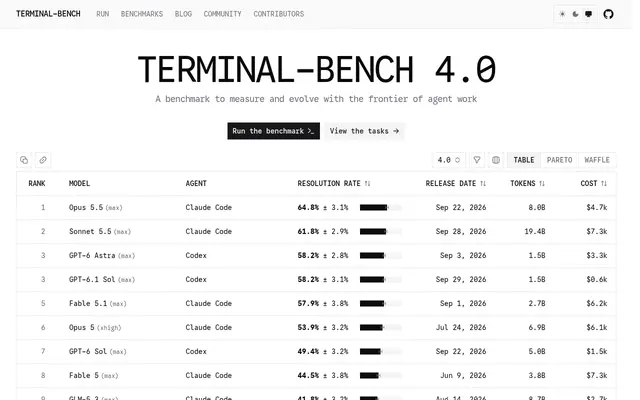
Benchmark for testing AI agents in real terminal environments
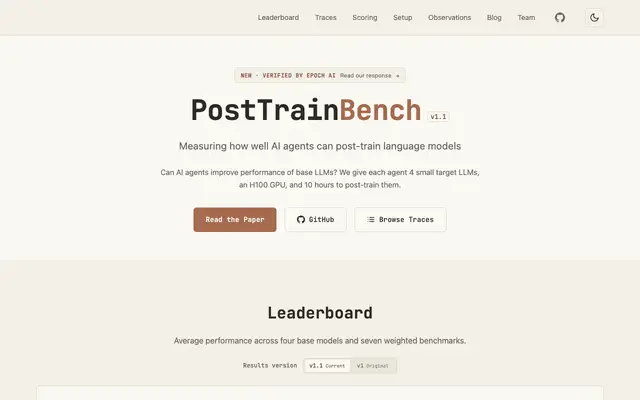
Benchmark measuring how well AI agents can improve base language models
Evaluation layer for AI analytics with governed ground truth and drift detection