pdf-inspector
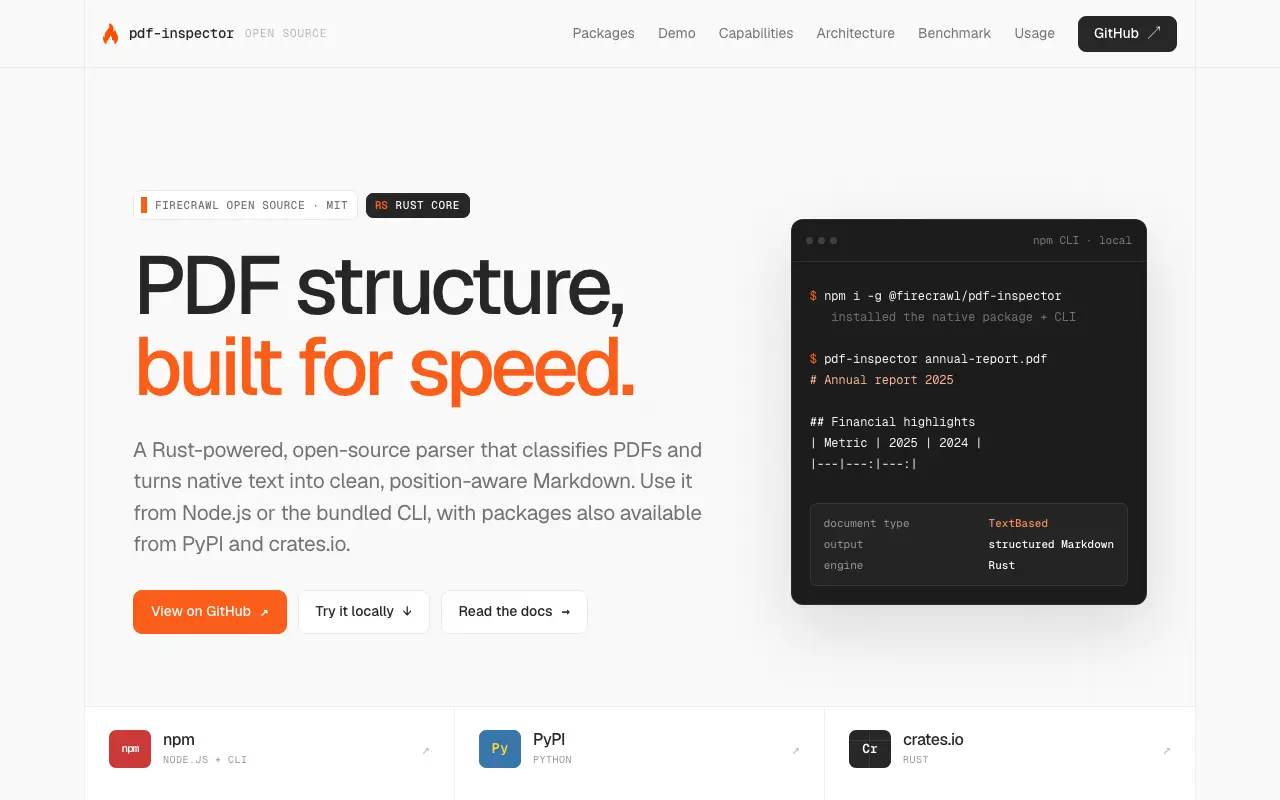
Fast, open-source PDF parser for structured Markdown extraction
 Visit firecrawl.github.io ↗
What is pdf-inspector?
pdf-inspector is a Rust-powered library that classifies PDFs and extracts native text into clean, position-aware Markdown. It detects whether PDFs are text-based, scanned, image-based, or mixed, then routes them appropriately—skipping expensive OCR for documents that don't need it. The tool handles multi-column layouts, tables, font decoding, and semantic formatting while keeping processing under 200ms for typical documents.
Available as npm, PyPI, and crates.io packages with a bundled CLI, plus browser WebAssembly support. The project describes itself as built by Firecrawl to handle text-based PDFs locally without relying on external OCR services. Developers can use it from Node.js, Python, Rust, or directly in browsers.
Momentum
Daily activity over the last 30 days: upvotes, unique visits, new GitHub stars and Hacker News points.
How do we know it's vibe coded?
vibetrend discovered pdf-inspector automatically. Evidence: GitHub firecrawl/pdf-inspector; repo has AGENTS.md, CLAUDE.md. View source.
Similar vibe-coded apps
 #1 this week
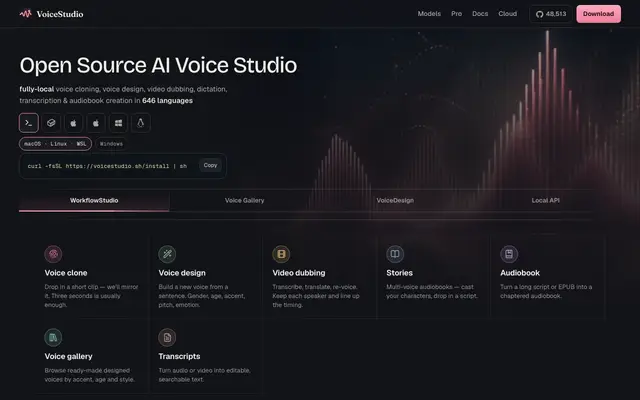
Open-source local voice cloning, dubbing, transcription, and audiobook creation
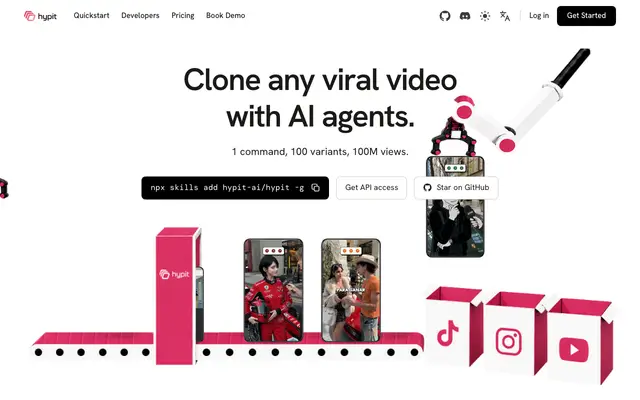
Clone viral videos with AI agents, generate 100 variants in one command
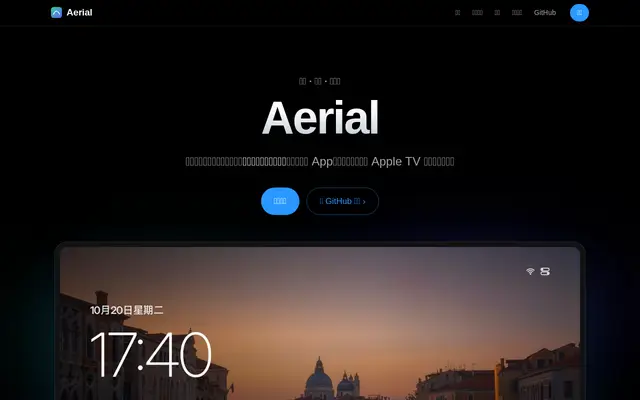
Clean Android TV launcher inspired by tvOS, ad-free with aerial screensavers
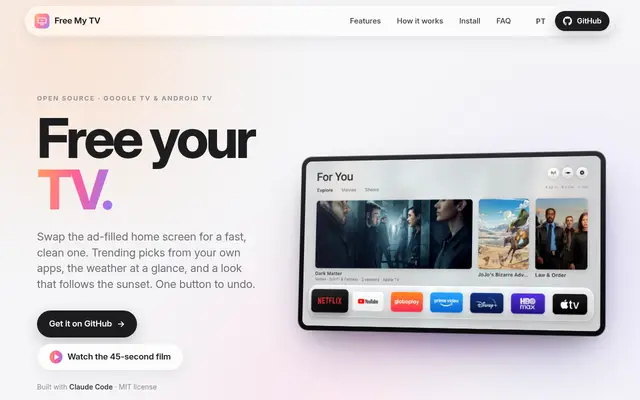
Ad-free home screen for Google TV with trending picks and live weather
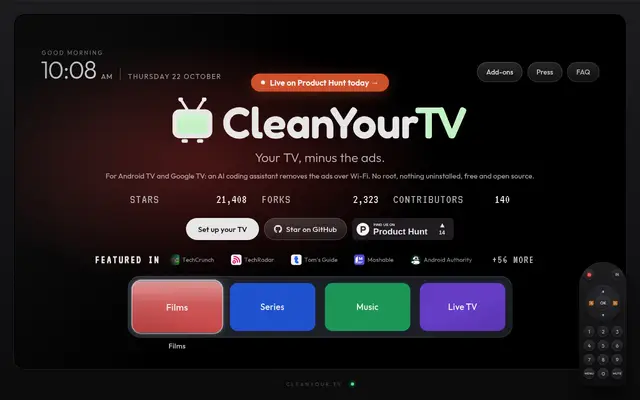
Remove ads and bloatware from Android TV and Google TV over Wi-Fi
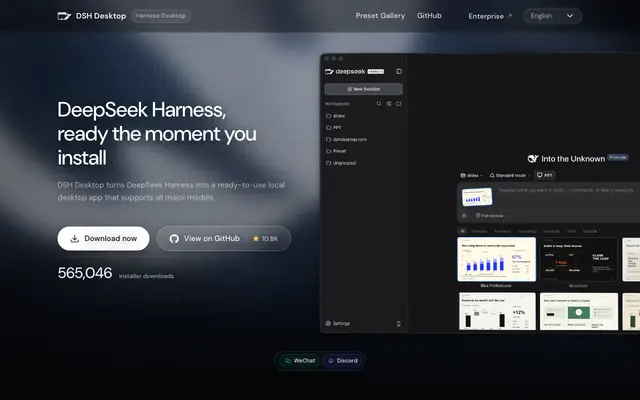
Desktop app for DeepSeek Harness with built-in model provider support