Rapid-MLX
OpenAI-compatible LLM server for Apple Silicon Macs, built on MLX
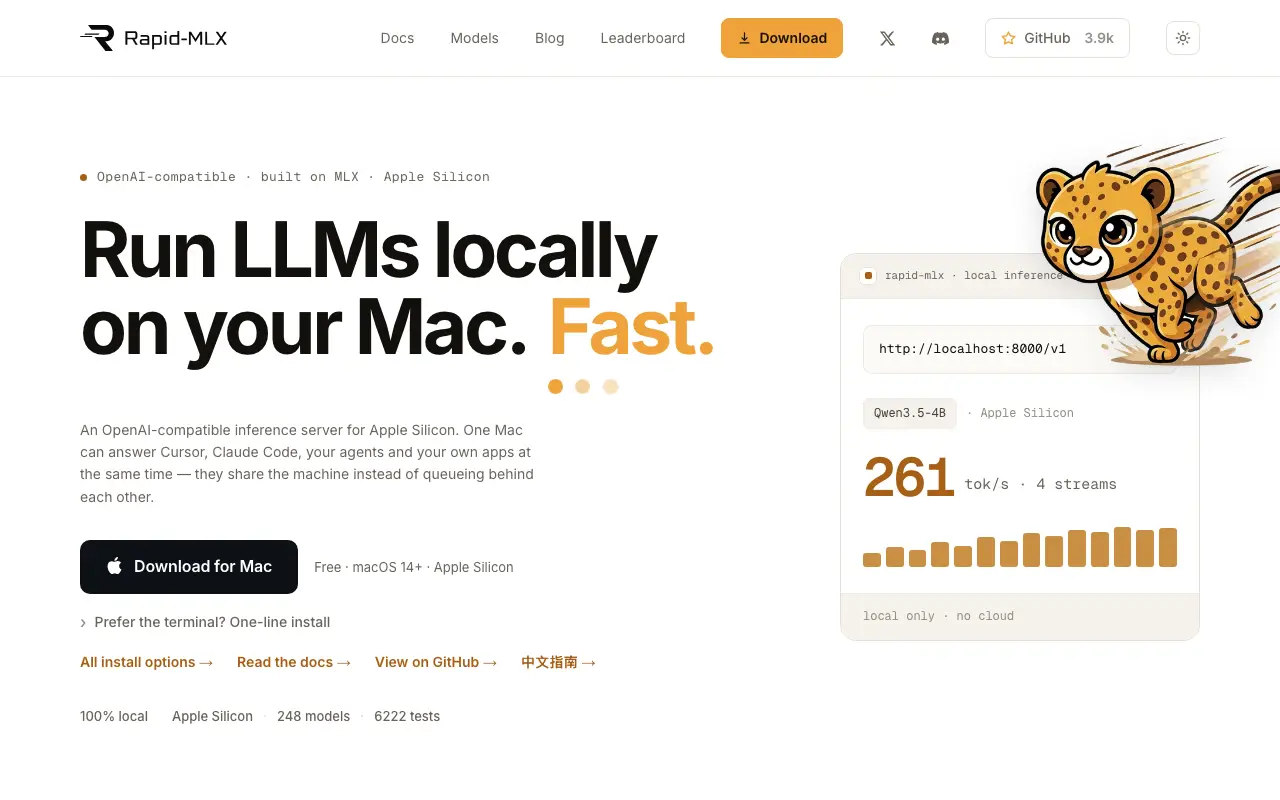 Visit rapidmlx.com ↗
What is Rapid-MLX?
Rapid-MLX is an open-source inference server that runs large language models locally on Apple Silicon Macs. It provides OpenAI and Anthropic-compatible APIs, allowing multiple applications like Cursor, Claude Code, and custom agents to query models concurrently on a single machine. The project emphasizes performance and reliability for tool calling in coding workflows.
Key features include continuous batching for concurrent requests, prompt caching with KV trimming for sub-100ms cached responses, and support for 231+ models across 15 families. Built on MLX, it achieves 261 tokens/second aggregate throughput across 4 concurrent streams on M3 Ultra hardware, with a desktop app and command-line interface available.
Momentum
Daily activity over the last 30 days: upvotes, unique visits, new GitHub stars and Hacker News points.
How do we know it's vibe coded?
vibetrend discovered Rapid-MLX automatically. Evidence: GitHub raullenchai/Rapid-MLX; repo has .claude, AGENTS.md. View source.
Similar vibe-coded apps
 #1 this week
Open-source local voice cloning, dubbing, transcription, and audiobook creation
 #2 this week
 #5 this week
Slash commands and agents for engineers using AI without compromising standards
 #6 this week
523 free lessons building AI systems from math and first principles
 #8 this week
 #10 this week
AI-powered design intelligence toolkit for building professional interfaces
Manage teams of AI agents to run your business from one dashboard
Persistent memory for AI agents across Claude Code, Cursor, and MCP clients