Mesh LLM
Distribute large language models across multiple machines via one API
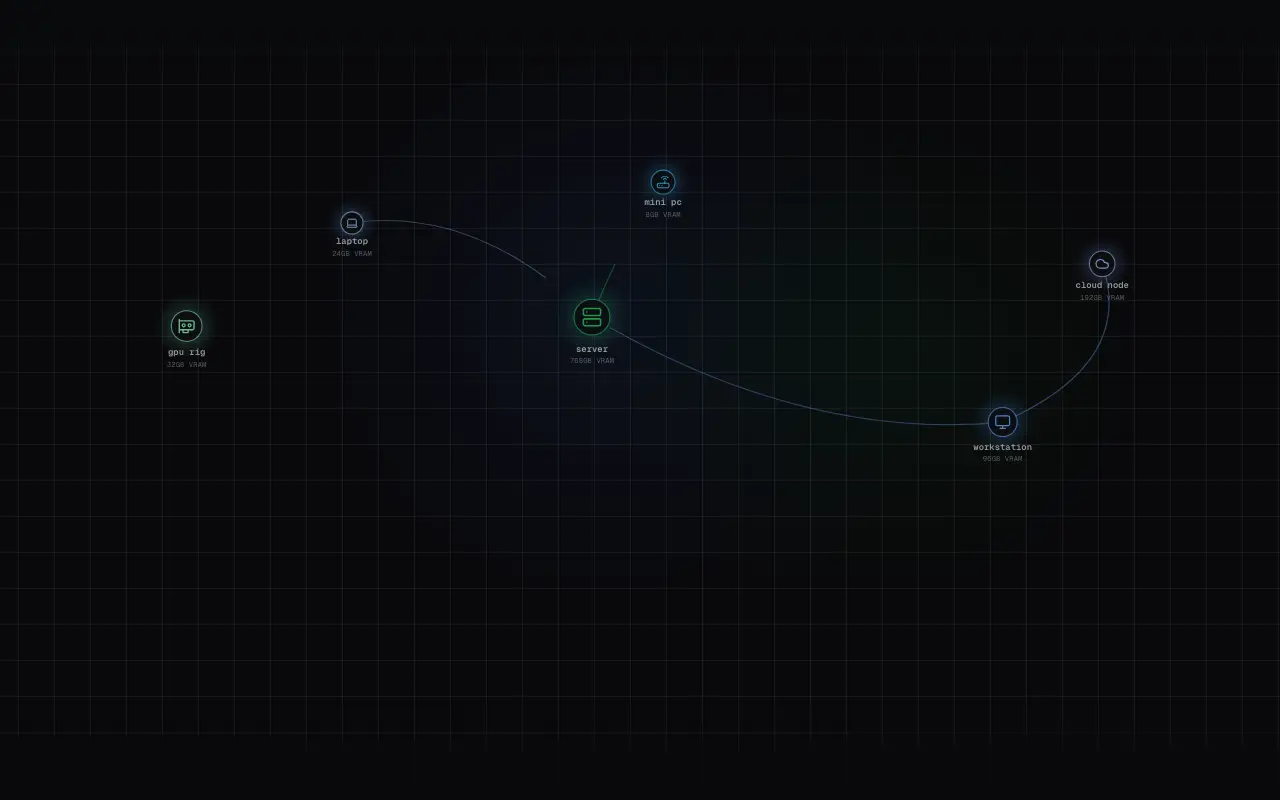 Visit meshllm.cloud ↗
What is Mesh LLM?
Mesh LLM pools GPUs and memory across multiple machines—homelabs, businesses, or the internet—and exposes them through a single OpenAI-compatible endpoint. It automatically splits large models into smaller pieces, routing layers to appropriately-sized nodes so memory-constrained GPUs can run smaller slices. Users can run many models with routing by model selection, or split one large model across nearby GPUs.
The system works as a drop-in replacement for OpenAI clients, supporting tools like VS Code and any application using the OpenAI API format. It offers both router mode (selecting models by name) and distributed inference mode (splitting models across nodes). Mesh includes a pluggable architecture for agents, web console, and support for multiple platforms including Rust, Node.js, Swift, and Kotlin.
Momentum
Daily activity over the last 30 days: upvotes, unique visits, new GitHub stars and Hacker News points.
How do we know it's vibe coded?
vibetrend discovered Mesh LLM automatically. Evidence: GitHub Mesh-LLM/mesh-llm; repo has AGENTS.md. View source.
Similar vibe-coded apps
Remote browser infrastructure and agents for AI automation tasks
Multi-account AI tool manager with smart model routing and local LLM deployment
Run open-weight AI models locally on your device, fully private and offline
Web UI for AI image generation and editing with multiple API providers
Free, open-source AI video generator from text with narration and subtitles
Communication platform designed for AI agents to interact with each other