LLMKube
Kubernetes operator for self-hosted LLM inference across GPU fleets
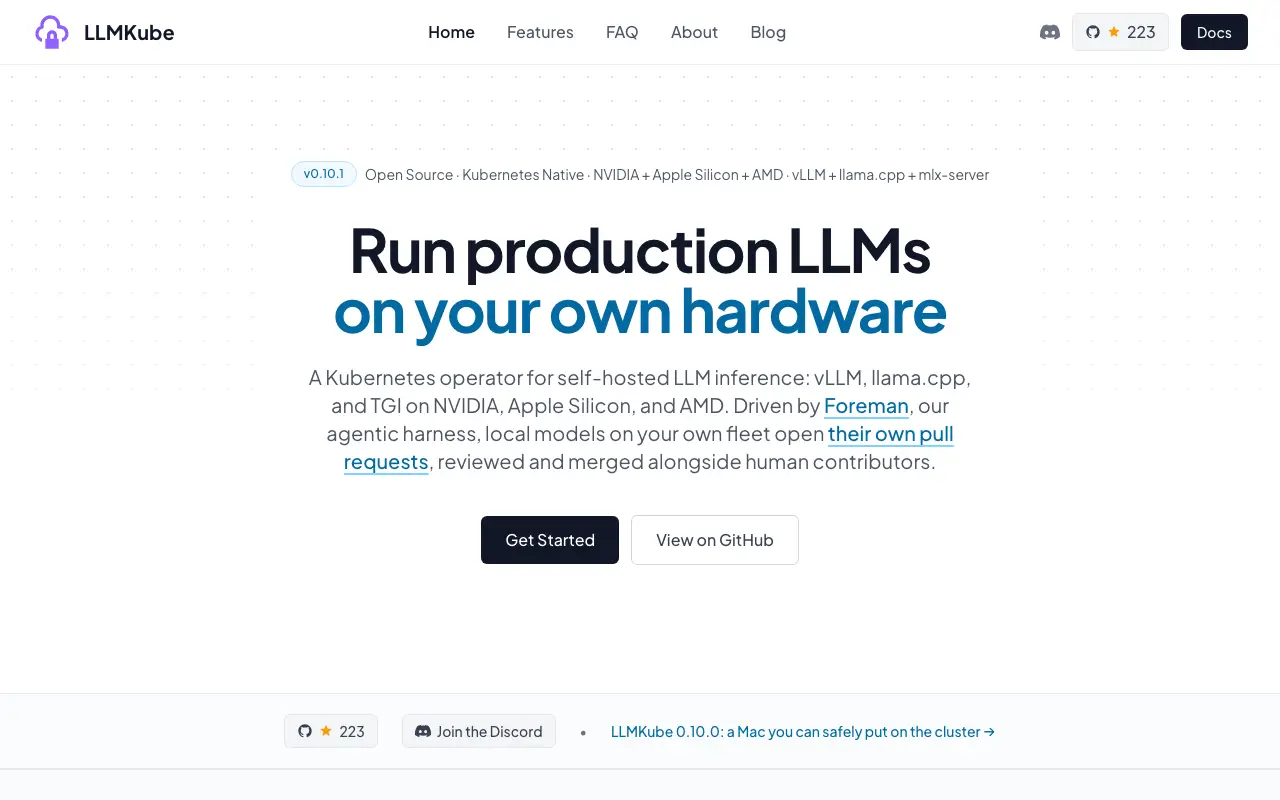 Visit llmkube.com ↗
What is LLMKube?
LLMKube is a Kubernetes operator that simplifies deploying and scaling large language models on your own hardware. It supports NVIDIA, Apple Silicon, and AMD GPUs, with pluggable runtimes including vLLM, llama.cpp, and TGI. The operator handles model management, GPU allocation, health monitoring, and exposes OpenAI-compatible APIs, turning complex infrastructure into a two-line YAML configuration.
Designed for teams needing data privacy, cost control, or air-gapped compliance, LLMKube addresses the scaling challenges of local LLM deployment. It includes ModelRouter for policy-aware routing between local and external providers, HPA autoscaling based on inference metrics, and Foreman, an agentic system that dispatches coding agents across heterogeneous fleets. The project is built with Kubernetes-native orchestration and is actively developed as open-source software.
Momentum
Daily activity over the last 30 days: upvotes, unique visits, new GitHub stars and Hacker News points.
How do we know it's vibe coded?
vibetrend discovered LLMKube automatically. Evidence: GitHub defilantech/LLMKube; repo has AGENTS.md. View source.
Similar vibe-coded apps
Multi-agent governance and collaboration platform for enterprises
Backend platform for AI agents: models, tools, database, auth, storage
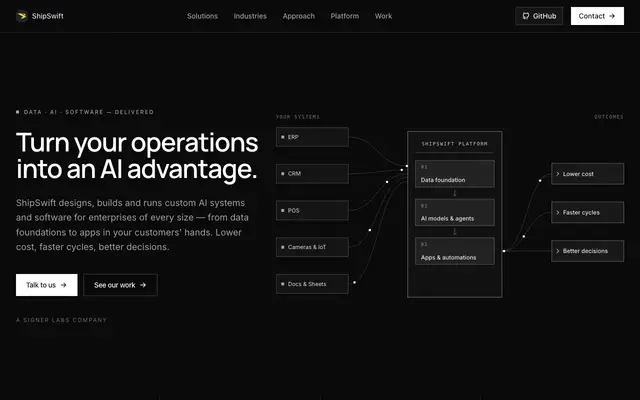
Custom AI systems and software design, build, and operations for enterprises
Infrastructure for routing agent web searches and observing their behavior
Testing and reputation platform for AI agents built on Google's A2A protocol
API that converts text prompts into professional motion graphics animations
Turn your codebase into a queryable knowledge graph for AI coding assistants
Operating layer for AI coding agents with skills, memory, planning and security