ChonkLM
Tiny language models running offline in your browser with on-device inference
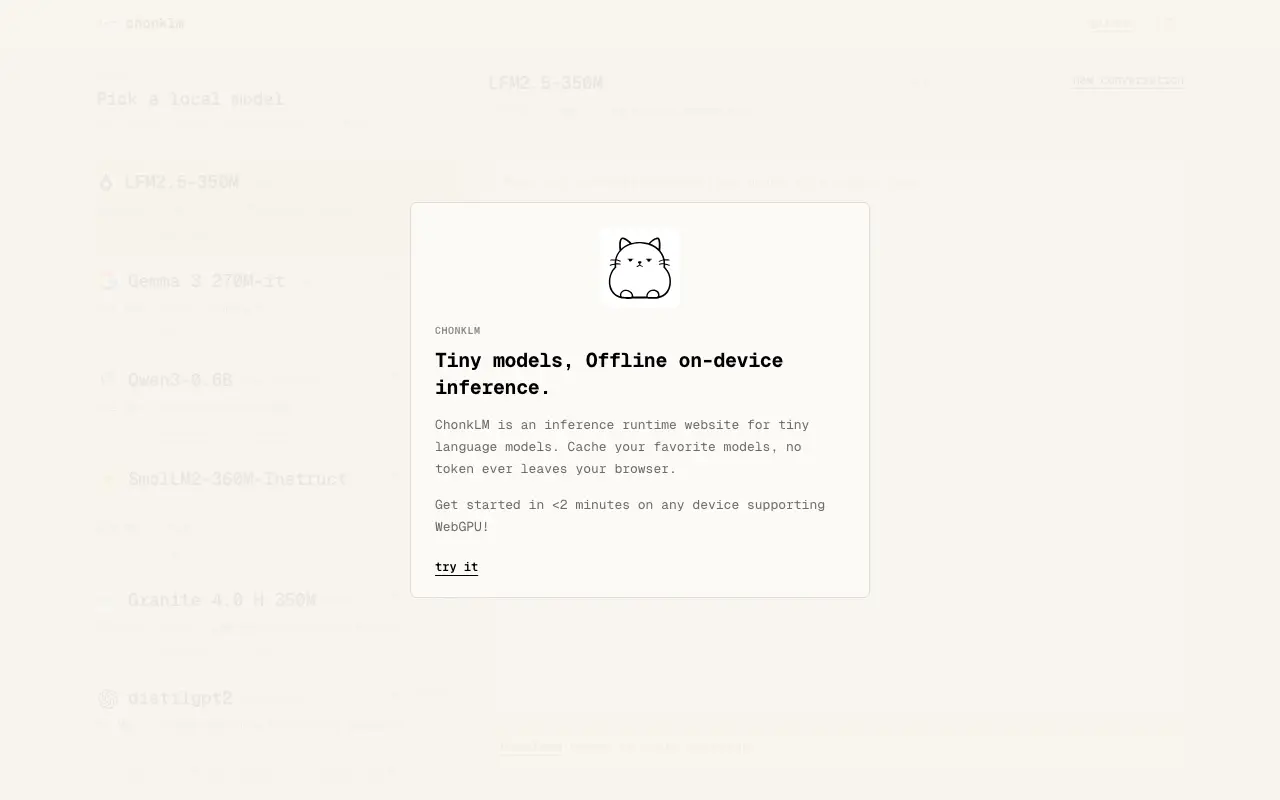 Visit chonklm.com ↗
What is ChonkLM?
ChonkLM is an inference runtime for small language models (under 500M parameters) that run directly in your browser using WebGPU. Models are cached locally, so no data leaves your device. It supports a curated selection of compact models including LFM2.5, Gemma 3, Qwen3, SmolLM2, and others, with sizes ranging from 33 MB to 462 MB.
Designed for developers and users exploring what tiny models can do, ChonkLM lets you chat with or extract structured data from these models without needing an API or server. The maker used Claude to help write the inference engine for GGUF model formats.
Momentum
Daily activity over the last 30 days: upvotes, unique visits, new GitHub stars and Hacker News points.
How do we know it's vibe coded?
vibetrend discovered ChonkLM automatically. Evidence: HN post: "I put my codex and claude to the task of writing WGSL to run inference". View source.
Similar vibe-coded apps
Clone viral videos with AI agents, generate 100 variants in one command
Self-hosted, open-source firewall automation and network security tools
Terminal overlay for on-demand AI agent access with approval-gated commands
Manage teams of AI agents to run your business from one dashboard
Free, open-source screen sharing for games, movies, and photos with friends
IDE to orchestrate multiple coding agents in one workspace
Multi-agent orchestration plugin for Claude Code with 19 specialized agents